How to Build a RAG Corpus with Mobile Proxies Without Collecting Garbage: A Step-by-Step Guide
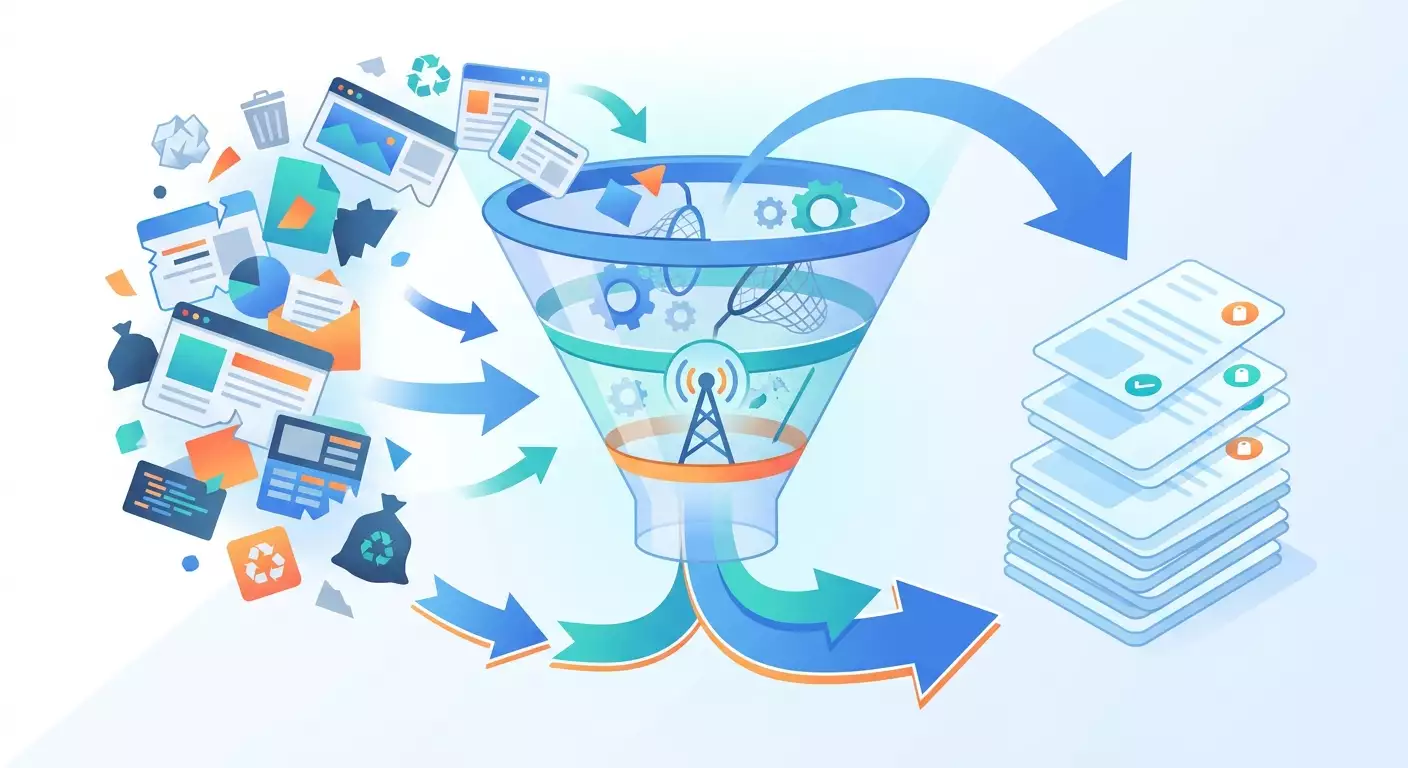
Table of contents
- Introduction: what you'll get and who this is for
- Preliminary preparation: tools, access, environment
- Basic concepts in plain language
- Step 1: define corpus boundaries and build a source map
- Step 2: connect a mobile proxy and verify requests go through it
- Step 3: write a careful collector with rate limits, rotation, and a journal
- Step 4: extract clean text from html and documents
- Step 5: filter out the garbage: deduplication, templates, quality, language
- Step 6: label metadata and assemble the final corpus
- Verifying the result: checklist and corpus testing
- Common mistakes and solutions when collecting a corpus for rag
- Advanced capabilities for power users
- Faq: common questions about corpus collection
- Conclusion: what's done and where to go next
Introduction: What You'll Get and Who This Is For
A RAG system is only as good as the corpus it answers from. You can take the strongest language model, hook up an expensive vector database, and still get confident nonsense on the output if your corpus is full of site menus, copyright footers, five versions of the same article, and pages that say "product temporarily unavailable." The model doesn't distinguish garbage from knowledge. It just finds similar fragments and pieces an answer together from them.
This step-by-step guide focuses on one stage: collecting the corpus. We won't cover how a vector database works, embedding selection, or chunk configuration—there are separate articles on the blog for those. Here we'll stop right at the boundary: you have a clean, labeled, deduplicated set of documents in JSONL format on your disk, ready to hand off to any indexing pipeline.
What you'll end up with:
- a list of sources with clear boundaries: what we collect, what we don't;
- a working Python collector that goes through a mobile proxy, respects rate limits, and doesn't knock other people's sites offline;
- a folder of raw pages and documents, each with metadata;
- a script that extracts the main text without navigation, ads, or template blocks;
- quality filters and deduplication that weed out garbage before it hits the index;
- a final corpus file and a report with numbers showing everything was done right.
Who this guide is for. Marketers and business owners who want to build a knowledge base for their niche and create an assistant on top of it. Media buyers who need a corpus of offers, landing pages, and ad platform rules. Developers who have already hooked proxies up to scripts and now want to do it carefully and systematically. The main text is written for beginners, and there's a dedicated section for advanced users at the end.
What you need to know beforehand. How to run commands in a terminal and open files in a text editor. A basic grasp of Python at the level of "I understand what a for loop does." And access to a mobile proxy: address, port, login, password, and the IP change link.
How much time it takes. Environment setup is about 30 minutes. Working through all the steps takes 3 to 5 hours, depending on corpus size. The actual collection of several thousand pages can run in the background for hours, but you don't need to be involved during that time.
Preliminary Preparation: Tools, Access, Environment
Before writing a single line of code, let's get your workspace in order. This will save you hours of debugging later.
System requirements
- A computer or server running Windows 10/11, macOS, or Linux. For collecting tens of thousands of pages, a rented VPS is more convenient, but a laptop is enough for your first corpus.
- At least 8 GB of RAM. Deduplicating large corpora loves memory.
- Free disk space: at least 5 GB. Raw HTML takes up 5-10 times more space than clean text, and we'll be storing both.
- A stable internet connection. Proxies add latency, so a slow home connection will noticeably stretch out collection time.
What to install
- Python 3.11 or newer. Download the installer from the official site; on Windows, check "Add Python to PATH" during installation. Verify in the terminal:
python --version. You should see something likePython 3.12.x. - A virtual environment. Create a project folder, for example
rag-corpus, cd into it, and runpython -m venv venv. Activate it: on Windowsvenv\Scripts\activate, on macOS and Linuxsource venv/bin/activate. You'll see(venv)at the start of your terminal prompt. - Libraries. Install them with a single command:
pip install requests trafilatura pypdf python-docx langdetect datasketch tqdm. Installation takes 1-3 minutes. - A text editor with code highlighting: VS Code, PyCharm Community, or any other.
Proxy access
Open your proxy service's dashboard. On your purchased mobile proxy's card, find four values: the host (IP address or domain name), the port for HTTP and the port for SOCKS5, the login, and the password. Separately, copy the IP change link: this is a URL that just needs a GET request to make the proxy get a new address from the carrier. Write all of this into a .env file in your project folder, not directly into the code.
Folder structure
Create the following folders inside your project: raw for raw pages, clean for extracted text, corpus for the final file, logs for journals. Empty folders at the start are fine.
Backups
A corpus takes a long time to collect, and losing it hurts. Make a rule with yourself: the raw folder is never overwritten, only appended to. After every major stage, archive the result: tar -czf raw_backup_2026-03-01.tar.gz raw/ on Linux and macOS, or use Windows' built-in archiver. If you make a mistake in the filters and delete something you shouldn't have, you can always go back to the raw data without re-collecting it.
Tip: Create a sources.md file right away and write down every decision in it: which sites you're taking, which sections you're excluding, and why. A month from now, when the assistant starts giving strange answers, this file will save you an evening.
Basic Concepts in Plain Language
If this is your first time collecting data for a RAG system, a few terms will come up in every step. Let's go through them briefly.
What RAG is and why the corpus matters more than the model
RAG (Retrieval-Augmented Generation) is an approach where the language model receives a selection of fragments from your knowledge base before answering. The model doesn't "know" your documents; it reads the retrieved pieces and answers based on them. Hence a simple rule: if there's garbage in the base, search will eventually pull that garbage up, and the answer will be based on "Subscribe to our newsletter" instead of an actual instruction. That's why the corpus collection stage can't be skipped.
Corpus, document, metadata
The corpus is the entire set of texts that will go into the RAG system. A document is one semantic unit: an article, a help page, a PDF guide, a product card. Metadata is the document's passport: where it came from, when it was collected, what language it's in, who wrote it, what section it belongs to. Without metadata, you can't update the corpus, explain to a user where an answer came from, or filter out outdated material.
Mobile proxy and why you need one for collection
A mobile proxy is an intermediary server that sends your requests to the internet through a cellular carrier's IP address. For corpus collection, it solves three practical problems. First: load distribution. Instead of hammering a site from one address, you come from different ones, and each source sees calm, infrequent traffic. Second: geography. Many sites show different content, prices, and availability depending on region, and a mobile proxy in the right city gives you exactly the version of the page your customers see. Third: stability of long sessions. IP rotation via link lets you keep collecting for hours without depending on one address.
Rotation is changing the IP address. It can be scheduled (every N minutes) or on demand (you hit the link when you need to). For corpus collection, the second is more convenient: switch source, switch address.
What counts as garbage
In the context of a corpus, garbage is anything that doesn't carry knowledge on your topic but takes up space in the index and ruins search:
- navigation, menus, footers, "breadcrumbs," subscription forms;
- exact and near-exact duplicates of the same text at different addresses;
- placeholder pages: "Page not found," "Product sold out," "Under maintenance";
- texts in another language if the corpus is monolingual;
- truncated pages where the proxy or site returned half the HTML;
- third-party content you don't have the right to use.
Legal framework
Collect only open data accessible without authentication, and your own documents. Respect the robots.txt file: it's a site's list of rules about which sections can be crawled automatically. Don't collect third parties' personal data: names with phone numbers, addresses, accounts. If you're building a corpus from your own internal documents, make sure you have the right to use them. In this guide, proxies are used as a tool for honest distributed collection, not as a way to do what a source has forbidden.
Step 1: Define Corpus Boundaries and Build a Source Map
Goal of this stage: get a file with a list of sources where, for each one, you've specified which URLs to take, which to exclude, how deep to crawl, and how many requests per minute are allowed.
The most common cause of a garbage corpus isn't technical errors—it's the absence of boundaries. Someone launches a collector "for the whole site," gets 40,000 pages of which 800 are on topic, and then spends a week cleaning. Let's do the opposite: map first, collect second.
Instructions
- Formulate the questions your RAG system should answer. Write 20-30 real user questions. For example, for a proxy service knowledge base: "How do I change the IP via a link," "Why is the proxy responding slowly," "Which ports are supported." These questions will become your test set at the verification stage.
- For each question, note where the answer lives. A help section, documentation, blog articles, PDF policies, product pages. Anything not on this list doesn't go into the corpus.
- Open each source in a browser and study its URL structure. Usually useful content sits under clear prefixes:
/help/,/docs/,/blog/,/faq/. Garbage sits under others:/tag/,/search?,/cart/,/author/, pagination pages like?page=. - Check the source's robots.txt. Open
https://domain/robots.txt. Find theDisallowlines: exclude those paths without discussion. If aCrawl-delayis listed there too, note it as the minimum pause between requests. - Find the sitemap. It's often listed in robots.txt on a
Sitemap:line, or lives at/sitemap.xml. A sitemap is a ready-made list of addresses that saves you from recursive link crawling and its associated garbage. - Determine the load. For small sites, set no more than 10-15 requests per minute. For large portals with a CDN, up to 30 is acceptable. If in doubt, go lower: the corpus isn't on fire.
- Determine the geography. If content depends on region (prices, delivery, availability), decide which city your collector should "look" from and pick the corresponding mobile proxy.
- Put it all into a
sources.jsonfile.
Example entry for one source:
[ {'name': 'help_center','sitemap': 'https://example.ru/sitemap.xml','include_prefixes': ['https://example.ru/help/', 'https://example.ru/docs/'],'exclude_patterns': ['/tag/', '/search', '?page=', '/print/'],'rate_per_minute': 12,'geo': 'RU-MOW','lang': 'ru','rotate_every': 40 }]The rotate_every field sets how many requests the collector makes before hitting the IP change link. Replace the single quotes with double quotes when saving to a real JSON file—they're shown here for clarity.
Warning: Don't add sites where useful content is only visible after logging into an account to your sources. First, it violates the user agreement of most platforms. Second, such a corpus can't be legally updated and distributed inside a company.
Tip: Create a separate source for your own documents: a folder with PDFs, DOCX files, and exports from your CRM or knowledge base. They don't need to be downloaded through a proxy, but we'll process and clean them with the same pipeline as web pages.
Verification: You have a sources.json file where each source has include prefixes, exclude patterns, a rate limit, and a language. Open 5 random addresses from the sitemap that match your filters and make sure each one has substantive text, not a catalog of links.
Possible problems
- The site has no sitemap. Build a list of addresses manually from a few index pages, or do a simple link crawl only within allowed prefixes, to a depth of 2.
- The sitemap has 100,000 addresses. Filter by prefix, then take a sample of 200 addresses, collect, and evaluate quality before running the whole thing.
- Useful content is scattered across different domains. Create a separate entry in
sources.jsonfor each domain, with its own limit and its own geography.
Step 2: Connect a Mobile Proxy and Verify Requests Go Through It
Goal of this stage: make sure the script really goes through the mobile proxy, rotation works, and latency is acceptable for collection.
Instructions
- Create a
.envfile in your project root and fill in the values from your dashboard:
PROXY_HOST=proxy.example.net PROXY_PORT=10000 PROXY_USER=your_login PROXY_PASS=your_password ROTATE_URL=https://changeip.example.net/?proxy_key=xxxxxxxxEach value on its own line. Add .env to .gitignore if you're using version control.
- Create a
proxy_check.pyfile with the following contents:
import os, time, requests from dotenv import load_dotenv load_dotenv() host = os.getenv('PROXY_HOST') port = os.getenv('PROXY_PORT') user = os.getenv('PROXY_USER') pwd = os.getenv('PROXY_PASS') rotate_url = os.getenv('ROTATE_URL') proxy_url = 'http://' + user + ':' + pwd + '@' + host + ':' + port PROXIES = {'http': proxy_url, 'https': proxy_url} def my_ip(): r = requests.get('https://api.ipify.org?format=json', proxies=PROXIES, timeout=30) return r.json()['ip'] print('IP without proxy:', requests.get('https://api.ipify.org?format=json', timeout=30).json()['ip']) t0 = time.time() ip1 = my_ip() print('IP through proxy:', ip1, 'in', round(time.time() - t0, 2), 'sec') print('Changing IP...') requests.get(rotate_url, timeout=60) time.sleep(8) ip2 = my_ip() print('IP after rotation:', ip2) print('Rotation worked:', ip1 != ip2)Install pip install python-dotenv first. In the real file, each line of code goes on its own line.
- Run it:
python proxy_check.py. - Read the output. The first IP should be your home or server IP. The second should be different and belong to a cellular carrier. The third should differ from the second, and the last line should show
True. - Measure latency. If a request through the proxy takes more than 5-6 seconds, collection will be slow. Check that your chosen proxy is geographically close to the target sites, or contact the service's support.
- Try SOCKS5 as an alternative. If the HTTP port gives unstable results, replace
http://inproxy_urlwithsocks5h://and the port with the SOCKS5 port from the dashboard. You'll needpip install requests[socks]. Thehsuffix matters: it makes the proxy resolve domain names itself.
Warning: Don't rotate IP more often than your plan allows. Most mobile proxies have a minimum interval between changes, usually from 30 seconds to 2 minutes. Too-frequent requests to the rotation link will either be ignored or temporarily block the feature.
Tip: Take five latency measurements in a row and note the median. You'll need this number in the next step to set timeouts correctly: the timeout should be about 4-5 times the typical latency.
Verification: The script outputs three different IP addresses, the line Rotation worked: True, and typical latency through the proxy doesn't exceed 3-4 seconds. If that's the case, the proxy is ready to work.
Possible problems
- Error 407 Proxy Authentication Required. Check your login and password, make sure there are no extra spaces. If the password contains
@or:characters, encode them withurllib.parse.quote. - Connection refused error or timeout. The proxy may be bound to your whitelisted IP. Go to the dashboard and add the current server address to the allowed list, or switch to login and password authentication.
- IP didn't change after rotation. Increase the pause after the rotation link request to 15-20 seconds. Some carriers don't issue a new address instantly.
- SSL errors. Update the
certifilibrary withpip install -U certifi. Don't disable certificate verification withverify=False: it's insecure.
Step 3: Write a Careful Collector with Rate Limits, Rotation, and a Journal
Goal of this stage: get a script that goes through the addresses from the sitemap, respects robots.txt and rate limits, goes through the proxy, changes IP on schedule, saves raw HTML, and keeps a journal showing every request.
It's important to understand the philosophy here. A good collector for a RAG system is slow, polite, and paranoidally detailed in its logs. A fast, aggressive crawler will net you a pile of truncated pages and 429 errors, and then you won't know which of those is garbage.
Instructions
- Create a
fetch.pyfile. The script structure: load settings, parse the sitemap, filter addresses, loop requests with pauses, save results. - Load the sitemap and filter addresses. A sitemap is XML where each address sits in a
loctag. Parse it with the standardxml.etree.ElementTree. Keep only addresses that start withinclude_prefixesand don't contain any of theexclude_patterns. Save the result tourls_help_center.txtand look at it with your own eyes. - Add robots.txt checking. Use
urllib.robotparser.RobotFileParser: load the file once per domain and, before each request, askcan_fetch(user_agent, url). Skip disallowed addresses and log them with arobots_disallowtag. - Set an honest User-Agent. For example:
CorpusCollector/1.0 (+contact: data@yourcompany.ru). The site owner should understand who came to them and how to get in touch. This isn't just ethics—it's practice: a clear agent is less likely to hit automatic restrictions. - Implement pauses. From
rate_per_minute, compute the base pause:60 / rate_per_minuteseconds. Add a random component of 20-40 percent so requests don't tick like a metronome. If robots.txt has aCrawl-delay, take the maximum of the two values. - Implement rotation. Count requests, and when the counter hits
rotate_every, call the IP change link, wait 10 seconds, and reset the counter. Also rotate when switching to the next source. - Handle responses. Save 200s.
requestshandles 301 and 302 itself, but record the final address: you'll need it for deduplication. Log 404s and skip. 429 or 503 means "too fast": pause for 5 minutes, increase the base pause by 1.5x, and retry once. If the retry doesn't help, skip and move on. - Save raw HTML with its passport. For each page, write one line to
raw/help_center.jsonl.
The key fragment of the saving and loop code:
import json, time, random, hashlib from datetime import datetime, timezone def save_raw(path, url, final_url, status, html, proxy_ip): rec = { 'url': url, 'final_url': final_url, 'status': status, 'fetched_at': datetime.now(timezone.utc).isoformat(), 'proxy_ip': proxy_ip, 'html_len': len(html), 'html_sha1': hashlib.sha1(html.encode('utf-8', 'ignore')).hexdigest(), 'html': html } with open(path, 'a', encoding='utf-8') as f: f.write(json.dumps(rec, ensure_ascii=False) + chr(10)) def fetch_one(session, url, proxies, headers, timeout): r = session.get(url, proxies=proxies, headers=headers, timeout=timeout, allow_redirects=True) return r.status_code, r.url, r.text for i, url in enumerate(urls): if not rp.can_fetch(UA, url): log('robots_disallow', url); continue if i > 0 and i % ROTATE_EVERY == 0: requests.get(ROTATE_URL, timeout=60); time.sleep(10) try: status, final_url, html = fetch_one(session, url, PROXIES, HEADERS, TIMEOUT) except Exception as e: log('error', url, str(e)); time.sleep(BASE_DELAY * 2); continue if status == 200 and len(html) > 2000: save_raw(RAW_PATH, url, final_url, status, html, current_ip) else: log('skip', url, status, len(html)) time.sleep(BASE_DELAY * random.uniform(1.0, 1.4))Note the len(html) > 2000 condition. A page with substantive text is almost never shorter than two kilobytes of HTML. This is the first, coarsest garbage filter, and it weeds out empty responses and placeholders right at the entrance.
- Run on a sample. Do your first run on 50 addresses. Look at the journal, open a couple of saved HTML files in a browser. Make sure they're the right pages.
- Run the full collection. On a server, use
nohup python fetch.py &orscreenso the process survives closing the terminal. Collecting 3,000 pages at 12 requests per minute takes about 4-5 hours.
Warning: Don't run multiple copies of the collector on the same site in parallel through one proxy. IP rotation doesn't cancel load limits on the source server. If you want to speed up, parallelize across different sites, not across one.
Tip: Log the proxy IP each request was made from. When a batch of truncated pages shows up during cleaning, you'll immediately see from the IP and timestamp whether it was a specific session's failure, and you can re-collect just that one.
Tip: Add resumption to your collector: before launching, read already-collected addresses from raw/*.jsonl and skip them. That way, a connection drop or server reboot won't make you start from scratch.
Verification: The raw folder contains a JSONL file, the line count is close to the number of addresses with 200 status in the journal, and a randomly chosen line contains the fields url, fetched_at, proxy_ip, and full HTML. The share of errors and skips in the journal doesn't exceed 5 percent.
Possible problems
- Lots of 429 responses. You're too fast for this site. Halve
rate_per_minute, increaserotate_everyso rotation doesn't look like a spike from new addresses. - Pages come back empty despite a 200 status. Content is rendered by JavaScript. Such sources require browser rendering, covered in the advanced section. For now, mark them in
sources.jsonwith aneeds_js: trueflag. - Collection is running but very slowly. Check the proxy latency from Step 2, make sure the timeout isn't set to 120 seconds when typical latency is 2, otherwise every stuck page eats two minutes.
- The script crashes on encoding. Use
r.textwith a check ofr.encoding; if the site reports encoding incorrectly, setr.encoding = r.apparent_encodingbefore reading.
Step 4: Extract Clean Text from HTML and Documents
Goal of this stage: turn raw HTML and files into clean text where only the page's main content remains: title, paragraphs, lists, tables, without menus, footers, ad inserts, and widgets.
This is the moment when corpus quality is either born or dies. The naive approach of "strip all tags" leaves menu items, "Buy" buttons, cookie banner text, and related article lists in the text. All of that later surfaces in the RAG system's answers.
Instructions for web pages
- Create an
extract.pyfile. It readsraw/*.jsonlline by line and writes the result toclean/*.jsonl. - Use the
trafilaturalibrary to extract the main text. It's trained to find a page's content area and discard template blocks.
import json, trafilatura def extract_text(html, url): downloaded = html result = trafilatura.extract( downloaded, url=url, include_comments=False, include_tables=True, include_links=False, favor_precision=True, output_format='json' ) if not result: return None data = json.loads(result) return { 'title': data.get('title'), 'text': data.get('text'), 'author': data.get('author'), 'date': data.get('date'), 'description': data.get('description') }- The
favor_precision=Trueparameter makes the library stricter: it prefers losing a chunk of text over grabbing a menu. For a RAG system's corpus, this is the right choice. If you notice that needed blocks are being lost, say tables of specs, switch tofavor_recall=Truefor that specific source. - Add a fallback method. If
trafilaturareturnsNoneor text shorter than 200 characters, try extracting content by a CSS selector you find by hand: open the page in a browser, press F12, find the block with the main text, copy its class, for examplearticle-body. UseBeautifulSoupto cut out just that block. Put the selector insources.jsonascontent_selector. - Normalize the text. Replace non-breaking spaces with regular ones, collapse three or more line breaks into two, trim leading and trailing spaces. Don't change case and don't remove punctuation: that will hurt search.
- Save along with the original metadata. Copy
url,final_url,fetched_atfrom the raw record, addsourcefromsources.json, the extraction fields, and the text length in characters.
Instructions for PDF and DOCX
- PDF. Use
pypdf: open the file, iterate through pages, callpage.extract_text(), and combine. Save the page number for each fragment: that's valuable metadata that will let a user find the location in the original. If text comes back empty, the PDF contains scans, not text: put such files in a separate folder; OCR is outside this guide's scope. - DOCX. Use
python-docx: iterate throughdocument.paragraphsanddocument.tables. Headings in Word have theHeading 1,Heading 2styles: save them as separate lines with a marker, as they make splitting documents later convenient. - Remove headers and footers. In PDF guides, each page repeats the company name, version number, and "Page 3 of 40." Collect all the document's lines, find those that repeat on more than half the pages, and delete them.
Warning: Don't delete tables for the sake of neatness. In guides, pricing, and specs, tables are exactly where the answers to specific questions live: "what's the limit," "how much does it cost," "which port." Save them line by line, separating cells with tabs or vertical bars.
Tip: After extraction, take 20 random documents and read them in full. Not skim—read. One such review finds more systemic problems than any automatic filter: for instance, you'll see that on every blog page, a "Read also" block with three headings got glued onto the end of the text.
Verification: The clean folder contains JSONL files. The record count is at least 80 percent of the raw page count. In 10 random records, the text starts with the title or first paragraph of the article, not with menu items, and ends with the last substantive paragraph, not with a "All rights reserved" signature.
Possible problems
- Too little text is extracted. The site has non-standard markup. Add a
content_selectorand a fallback path viaBeautifulSoup. - Buttons and menu items remain in the text. Enable
favor_precision, and for stubborn cases add a list of stop lines: delete short lines like "Share," "Read more," "Back to top" if they stand on their own line. - PDF returns text backwards or with broken words. Try
pdfplumberinstead ofpypdf; it handles columns better.
Step 5: Filter Out the Garbage: Deduplication, Templates, Quality, Language
Goal of this stage: weed out duplicates, placeholders, template blocks, texts in a foreign language, and documents that are too short or broken, keeping only what carries knowledge.
Even after careful extraction, 15 to 40 percent of the corpus is still garbage. That's normal. What's not normal is letting it into the index.
Instructions
- Create a
filter.pyfile that readsclean/*.jsonl, applies filters in sequence, writes passing documents tocorpus/filtered.jsonl, and rejected ones tocorpus/rejected.jsonlwith a reason. - Filter 1: minimum length. Documents shorter than 300 characters are almost always placeholders, teasers, or extraction failures. Reject with reason
too_short. For product cards, the threshold can be lowered to 150. - Filter 2: placeholder stop phrases. Make a list of phrases that indicate an empty page: "page not found," "product unavailable," "access restricted," "enable javascript," "under maintenance." If such a phrase appears in the first 300 characters and the whole text is shorter than 1,500, reject with reason
placeholder. - Filter 3: language. Use
langdetect.detecton the first 1,000 characters. If the language doesn't match the source's declared language, reject with reasonwrong_lang. Note that the detector errs on short texts, so apply it after the length filter. - Filter 4: exact duplicates. Normalize the text: lowercase, collapse whitespace, remove punctuation. Compute
sha1. If the hash has already appeared, reject with reasonexact_dupand save a link to the original. Typical sources of exact duplicates: the same page underhttpandhttps, withwwwand without, with a?utm_sourceparameter and without, plus print pages. - Filter 5: near duplicates. This is where MinHash from the
datasketchlibrary comes in. Split the normalized text into 5-word shingles, build aMinHashwith 128 permutations, put it into aMinHashLSHwith a threshold of 0.85. A document that already has a similar neighbor in the index gets rejected with reasonnear_dup. This removes versions of the same article with different dates, product pages that differ only by color, and republished news.
from datasketch import MinHash, MinHashLSH def shingles(text, k=5): words = text.split() return set(' '.join(words[i:i+k]) for i in range(max(1, len(words) - k + 1))) lsh = MinHashLSH(threshold=0.85, num_perm=128) def is_near_dup(doc_id, norm_text): m = MinHash(num_perm=128) for sh in shingles(norm_text): m.update(sh.encode('utf-8')) if lsh.query(m): return True lsh.insert(doc_id, m) return False- Filter 6: template lines. Collect all lines across all documents from one source and count what percentage of documents each appears in. Lines that appear in more than 30 percent of documents and are shorter than 200 characters are templates: disclaimers, signatures, subscribe prompts. Delete them from all documents. This isn't a document-level rejection, but a within-document cleanup.
- Filter 7: text quality. Compute simple metrics: the share of letters among all characters should be above 0.6; average word length between 3 and 12; the share of lines ending in a period above 0.3 for articles. Documents outside these bounds are usually code tables, dumps, or broken extractions. Reject with reason
low_quality, but be sure to eyeball the rejected ones: for technical documentation, the thresholds need to be loosened. - Filter 8: truncated pages. Compare
html_lenfrom the raw record with the median for that source. If the HTML is shorter than 30 percent of the median and the text cuts off mid-sentence without a period, it's a truncated response. Reasontruncated. Write such addresses torecollect.txtand re-collect them through the proxy at Step 3. - Run the filter and study the report. The script should output a table: how many documents at the input, how many rejected for each reason, how many remain.
Warning: Never delete files from clean or raw during filtering. The filter only writes new files. If the MinHash threshold turns out to be too aggressive and you lose 40 percent of useful documents, you just change the number and re-run the script in two minutes.
Tip: A 0.85 threshold for near duplicates is good for articles and help docs. For product cards from one brand that differ only by size or volume, it will collapse them into one. Decide in advance whether your RAG system needs all variants, and either raise the threshold to 0.95 or merge variants into one document with a differences table back at the extraction stage.
Tip: Rejected documents aren't waste—they're debugging material. Once a week, open rejected.jsonl, filter by reason, and look at 10 random records. If useful pricing tables regularly show up among low_quality, the thresholds need fixing.
Verification: The filter report shows a reasonable picture: total rejection between 10 and 40 percent, with duplicates making up a noticeable share, and the truncated reason accounting for no more than 2-3 percent. The filtered.jsonl file has no two documents with identical normalized text, and 10 random records look like completed articles or documentation sections.
Possible problems
- Rejection above 60 percent. Most likely the quality thresholds are too strict, or there's a normalization bug that made all texts look alike. Print 20 random rejected ones and find the systemic cause.
- MinHash runs very slowly. On a corpus of more than 100,000 documents, reduce
num_permto 64 or compute by source separately. - The language detector flags Russian texts as Bulgarian or Macedonian. This happens on short fragments with many proper nouns. Detect language on the first 2,000 characters and accept any from a group of closely related languages as a match.
Step 6: Label Metadata and Assemble the Final Corpus
Goal of this stage: get a single corpus/corpus_v1.jsonl file where each document has a stable identifier, a full set of metadata, and is ready to hand off to the indexing pipeline.
Metadata is what separates a corpus from a pile of text. It lets you update individual sources, explain the origin of an answer to a user, filter by date and section, and, most importantly, avoid redoing all the work a month later.
Instructions
- Define the document schema. Lock it into a
schema.mdfile and don't change it without a corpus version bump. Recommended minimum:
doc_id: a stable identifier, for examplesha1offinal_url, so that on re-collection the document gets the same id;source: the source name fromsources.json;urlandfinal_url;title;section: the site section computed from the first path segment after the prefix, for examplehelp/proxies;lang;published_at: publication date, if extracted;fetched_at: collection date;geo: the proxy region it was collected from;text;text_len,text_sha1;corpus_version: for examplev1.
- Compute the section. Parse
final_urlwithurllib.parse.urlparse, take the path, remove the source prefix, keep one or two segments. The section will later become a filter in the RAG system: a user asks about billing, and search goes first through thebillingsection. - Normalize dates. Bring all dates to ISO 8601 in UTC. If the publication date isn't found, leave the field empty rather than substituting the collection date: they're different things, and confusing them is dangerous when filtering outdated material.
- Add the title to the text. If
textdoesn't start withtitle, insert the title as the first line. The title carries keywords that matter for search. - Sort and write. Sort documents by
sourceandfinal_url, write tocorpus/corpus_v1.jsonl. Alongside, placecorpus/manifest_v1.jsonwith the document count by source, assembly date, schema version, and filter parameters. - Make an archive. Archive
corpus,sources.json,schema.md, and thelogsfolder. This archive is a reproducible version of your corpus.
Tip: Keep personal data out of the corpus entirely. If help texts contain examples like "Ivan Petrov, +7 900...," replace them with placeholders already at the corpus assembly stage. A RAG system shouldn't be able to produce someone's phone number, even if it was publicly available.
Verification: The corpus_v1.jsonl file opens, each line is valid JSON with schema fields, all documents have a unique doc_id, and all have source, lang, fetched_at, text filled in. The manifest_v1.json file contains a summary matching the line count.
Possible problems
- Different addresses lead to one document and produce different doc_ids. Compute the id from
final_urlafter redirects, stripping query parameters and the trailing slash. - Dates are extracted in different formats. Use
dateutil.parser.parsewithdayfirst=Truefor Russian-language sources.
Verifying the Result: Checklist and Corpus Testing
The corpus is collected. Before taking it to indexing, let's test it as a product, not as a file.
Checklist
- There's a
sources.jsonwith boundaries for each source and specified rate limits. - All requests went through the mobile proxy; the journal has a
proxy_ipfor every request. - The share of collection errors in the journal doesn't exceed 5 percent, 429 responses are under 1 percent.
- At least 80 percent of documents were extracted from raw pages.
- Filtering rejection is between 10 and 40 percent, with every rejection reason named.
- The corpus has no exact duplicates by normalized text.
- Every document has its mandatory metadata filled in.
- There's an archive with raw data, the corpus, logs, and settings.
How to test
- Test on the questions from Step 1. Take your 20-30 questions. For each, use a simple substring search or
grepto find a document in the corpus containing the answer. Goal: at least 90 percent of questions have coverage. If a question isn't covered, find the page with the answer in a browser and figure out why it didn't make it: wasn't in the sitemap, was rejected by filters, text got truncated. - Garbage test. Find the strings "subscribe," "cart," "cookie," "all rights reserved," "read also" in the corpus. Every occurrence is a suspicion. A handful are acceptable if they're part of substantive text; dozens of occurrences mean the template filter needs work.
- Truncation test. Count documents whose text ends with something other than a period, exclamation mark, question mark, or closing parenthesis. Their share should be under 5 percent. Eyeball the rest.
- Distribution test. Plot a histogram of document lengths. A healthy help or blog corpus has a peak around 2,000-8,000 characters and a long tail. A sharp peak near the minimum threshold signals placeholders that slipped through.
- Geography test. If content depends on region, open 5 pages with prices or availability and compare with what a person in the target city sees. Discrepancies mean the proxy was selected from the wrong region, or the site determines region by cookie rather than IP.
Success indicators
The corpus is ready if test question coverage is above 90 percent, the share of documents with garbage signs is below 3 percent, and the manifest allows you to fully reproduce the assembly. Only then does the corpus go to the RAG system's indexing pipeline.
Common Mistakes and Solutions When Collecting a Corpus for RAG
Problem: menu items and subscribe prompts appear in the assistant's answers. Cause: text extraction ran in recall mode instead of precision mode, and the template filter never ran. Solution: enable favor_precision, implement removal of lines that repeat in more than 30 percent of a source's documents, and re-extract clean from raw without re-downloading.
Problem: the assistant answers from an outdated version of a guide. Cause: the corpus has both the old and new version of the article; near duplicates weren't rejected, or the threshold is too high. Solution: lower the MinHash threshold to 0.8 for sources with versioning; on conflict, keep the document with the later published_at.
Problem: some pages were collected empty with a 200 status. Cause: content is built by JavaScript in the browser. Solution: mark the source needs_js and use Playwright rendering from the advanced section, or find the site's API or RSS where content comes ready-made.
Problem: collection stops on 429 and 503 errors. Cause: too high a request rate; IP rotation was used instead of lowering load. Solution: reduce the rate to 6-8 requests per minute, increase the random spread of pauses, and pause 5-10 minutes on the first 429. Remember that the load limit is about respecting the source, not about the number of addresses.
Problem: after rotation, the site shows content from another region. Cause: the mobile proxy issued an IP from another city, or the site determined region by cookie from the previous session. Solution: pin the desired region in your proxy dashboard and reset the requests session after each rotation so cookies don't carry over.
Problem: the corpus is assembled but question coverage is 60 percent. Cause: source boundaries were set too narrowly; useful pages got rejected by prefixes. Solution: take the uncovered questions, find the answers in a browser, look at their addresses, and expand include_prefixes.
Problem: deduplication ate product cards differing by specs. Cause: the near-duplicate threshold is too low for uniform texts. Solution: for catalog sources, raise the threshold to 0.95, or merge variants of one product into a single document at the extraction stage.
Problem: PDF texts come out as one continuous line without paragraphs. Cause: pypdf loses formatting. Solution: switch to pdfplumber or pymupdf, and reconstruct paragraphs from double line breaks and indents.
Problem: personal data ended up in the corpus. Cause: there was no anonymization stage. Solution: add detection of phone numbers, emails, and names via simple patterns and replace them with placeholders before writing to the corpus; send ambiguous documents for manual review.
Advanced Capabilities for Power Users
If the basic pipeline works, here's where to take it next.
Rendering JavaScript pages through a proxy
Install pip install playwright and playwright install chromium. Launch the browser with the parameter proxy={'server': 'http://HOST:PORT', 'username': USER, 'password': PASS}. Wait for the main content selector with page.wait_for_selector, not fixed seconds. Grab page.content() and store it in the same raw format so subsequent steps don't change. Rendering is 5-10 times slower than regular requests, so apply it only to sources with the needs_js flag and lower the rate to 3-5 pages per minute.
Incremental corpus updates
Store each document's text_sha1 in the manifest. On the next collection, download the pages but extract and filter only those whose HTML hash changed or that were collected more than 30 days ago. Use If-Modified-Since and ETag headers: many sites will return 304 without a body, and you'll save proxy traffic. Each update gets a new corpus version: v2, v3, and old archives aren't deleted.
Multi-regional corpus
If a business has branches and source content depends on city, set up several mobile proxies with different geographies. Collect the same page from each region, store geo in metadata, and deduplicate only within a region. The RAG system can then answer "in Kazan delivery is 2 days, in Novosibirsk 4," based on real regional versions of pages.
Quality scoring instead of hard thresholds
Instead of threshold-based rejection, compute a quality score from 0 to 1 for each document from the same metrics: length, share of letters, share of completed sentences, line repetition. Store the score in metadata. Then the indexing pipeline can decide what to take, and search can rank reliable documents higher.
Semantic deduplication
MinHash catches lexical duplicates. It will miss paraphrases of the same instruction in different words. To catch those, compute document embeddings and look for pairs with cosine similarity above 0.95. This is already the boundary with the indexing stage, so this is just a mention: decide where to draw the line and don't do the same work twice.
Collection monitoring
Derive metrics from the journal: requests per minute, share of 200 codes, average latency, rotation count. A simple matplotlib dashboard or a terminal table every 10 minutes will show degradation before you discover 500 empty pages in the morning.
FAQ: Common Questions About Corpus Collection
Do I have to use a mobile proxy to collect a corpus? For your own documents and small sources, no. A proxy becomes necessary when there are many sources, collection runs for hours, the regional version of content matters, or you don't want to create noticeable load on a site from one address.
How often should I change IP during collection? A guideline: every 30-60 requests, or when switching to another source. More often isn't needed: the point of rotation is load distribution and session stability, not frequency for its own sake. Frequent rotation without lowering the overall pace doesn't reduce load.
How many documents does a working RAG system need? For an assistant on one product, 200-500 quality documents is often enough. For a broad niche, several thousand. Quality beats volume: 500 clean articles will give better answers than 20,000 with garbage.
Can I collect from social networks and marketplaces? Only open pages within the platform's rules and robots.txt, without personal data. Many platforms have official APIs for getting content—start there.
What about images and videos? For a text corpus, save only captions, alt texts, and transcripts if they're on the page. The files themselves don't go into the corpus.
Why can't I just download the whole site with a downloader program? You can, but you'll get tens of thousands of files without metadata, with duplicates, service pages, and no journal. Then you'll have to do all the steps in this guide in reverse, only harder.
How do I know the filters didn't remove something needed? Look at rejected.jsonl by each reason, a sample of 10-20 records. And check test question coverage: if answers disappeared, look for them among the rejected.
Should I chunk documents at this stage? No. Splitting into fragments is part of indexing and depends on the embedding model and context size. The corpus's job is to provide whole documents with metadata and heading markup that a chunker can use to split meaningfully.
How do I update the corpus without rebuilding everything? Store hashes, use If-Modified-Since conditional requests, and version the corpus. More in the advanced section.
What if a site forbids automatic collection in robots.txt? Respect the prohibition. Write to the owner; often they'll give you an export, API, or permission. A corpus collected against a source's rules creates risks for the whole project.
Conclusion: What's Done and Where to Go Next
You've gone the whole way from idea to a finished corpus. You defined boundaries and built a source map with limits and geography. You connected a mobile proxy and confirmed rotation works. You wrote a polite collector that respects robots.txt, distributes load, and keeps a detailed journal. You extracted clean text from HTML, PDF, and DOCX. You weeded out duplicates, placeholders, templates, and broken pages with named reasons. You labeled metadata and assembled a versioned corpus with a manifest. You tested it on real questions.
The main result isn't the file on disk—it's a reproducible process. A month from now, you'll run it again and get an updated corpus in a couple of hours, not a week. And when the RAG system starts giving strange answers, you'll know exactly where to look for the cause: in the collection journal, the filter report, or the manifest.
What to do next. Hand corpus_v1.jsonl to the indexing pipeline: chunking, embeddings, vector database. That's covered in related blog articles. Set up regular scheduled runs of the collector with incremental updates. Expand the source map as the number of uncovered questions grows. If your business is regional, add proxies for the right cities and collect regional versions of content.
Where to grow. Master browser rendering for complex sites, document quality scoring instead of hard thresholds, semantic deduplication, and collection monitoring. Each of these steps improves answer quality more than a model change. Clean data is the cheapest improvement to your RAG system you have. Happy collecting.